Accepted Paper
December 2026
IEEE Spoken Language Technology Workshop '26
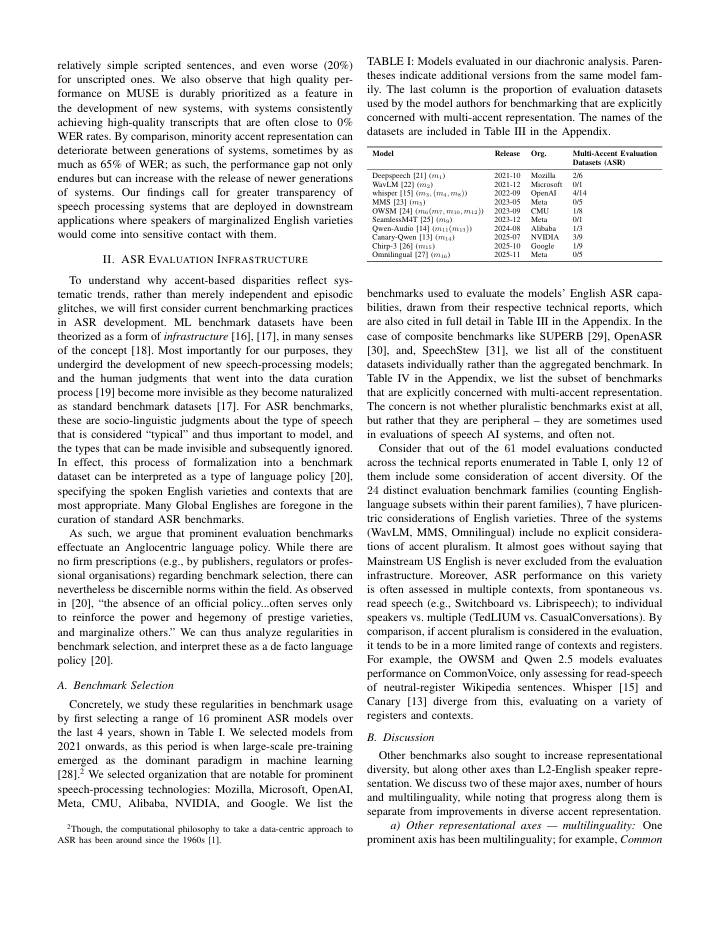
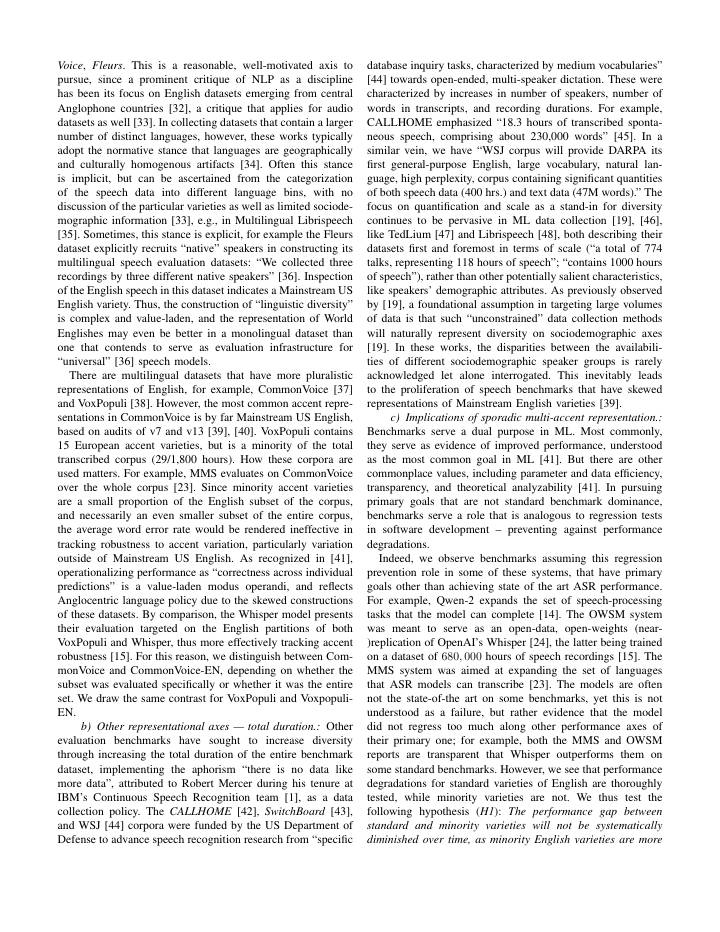
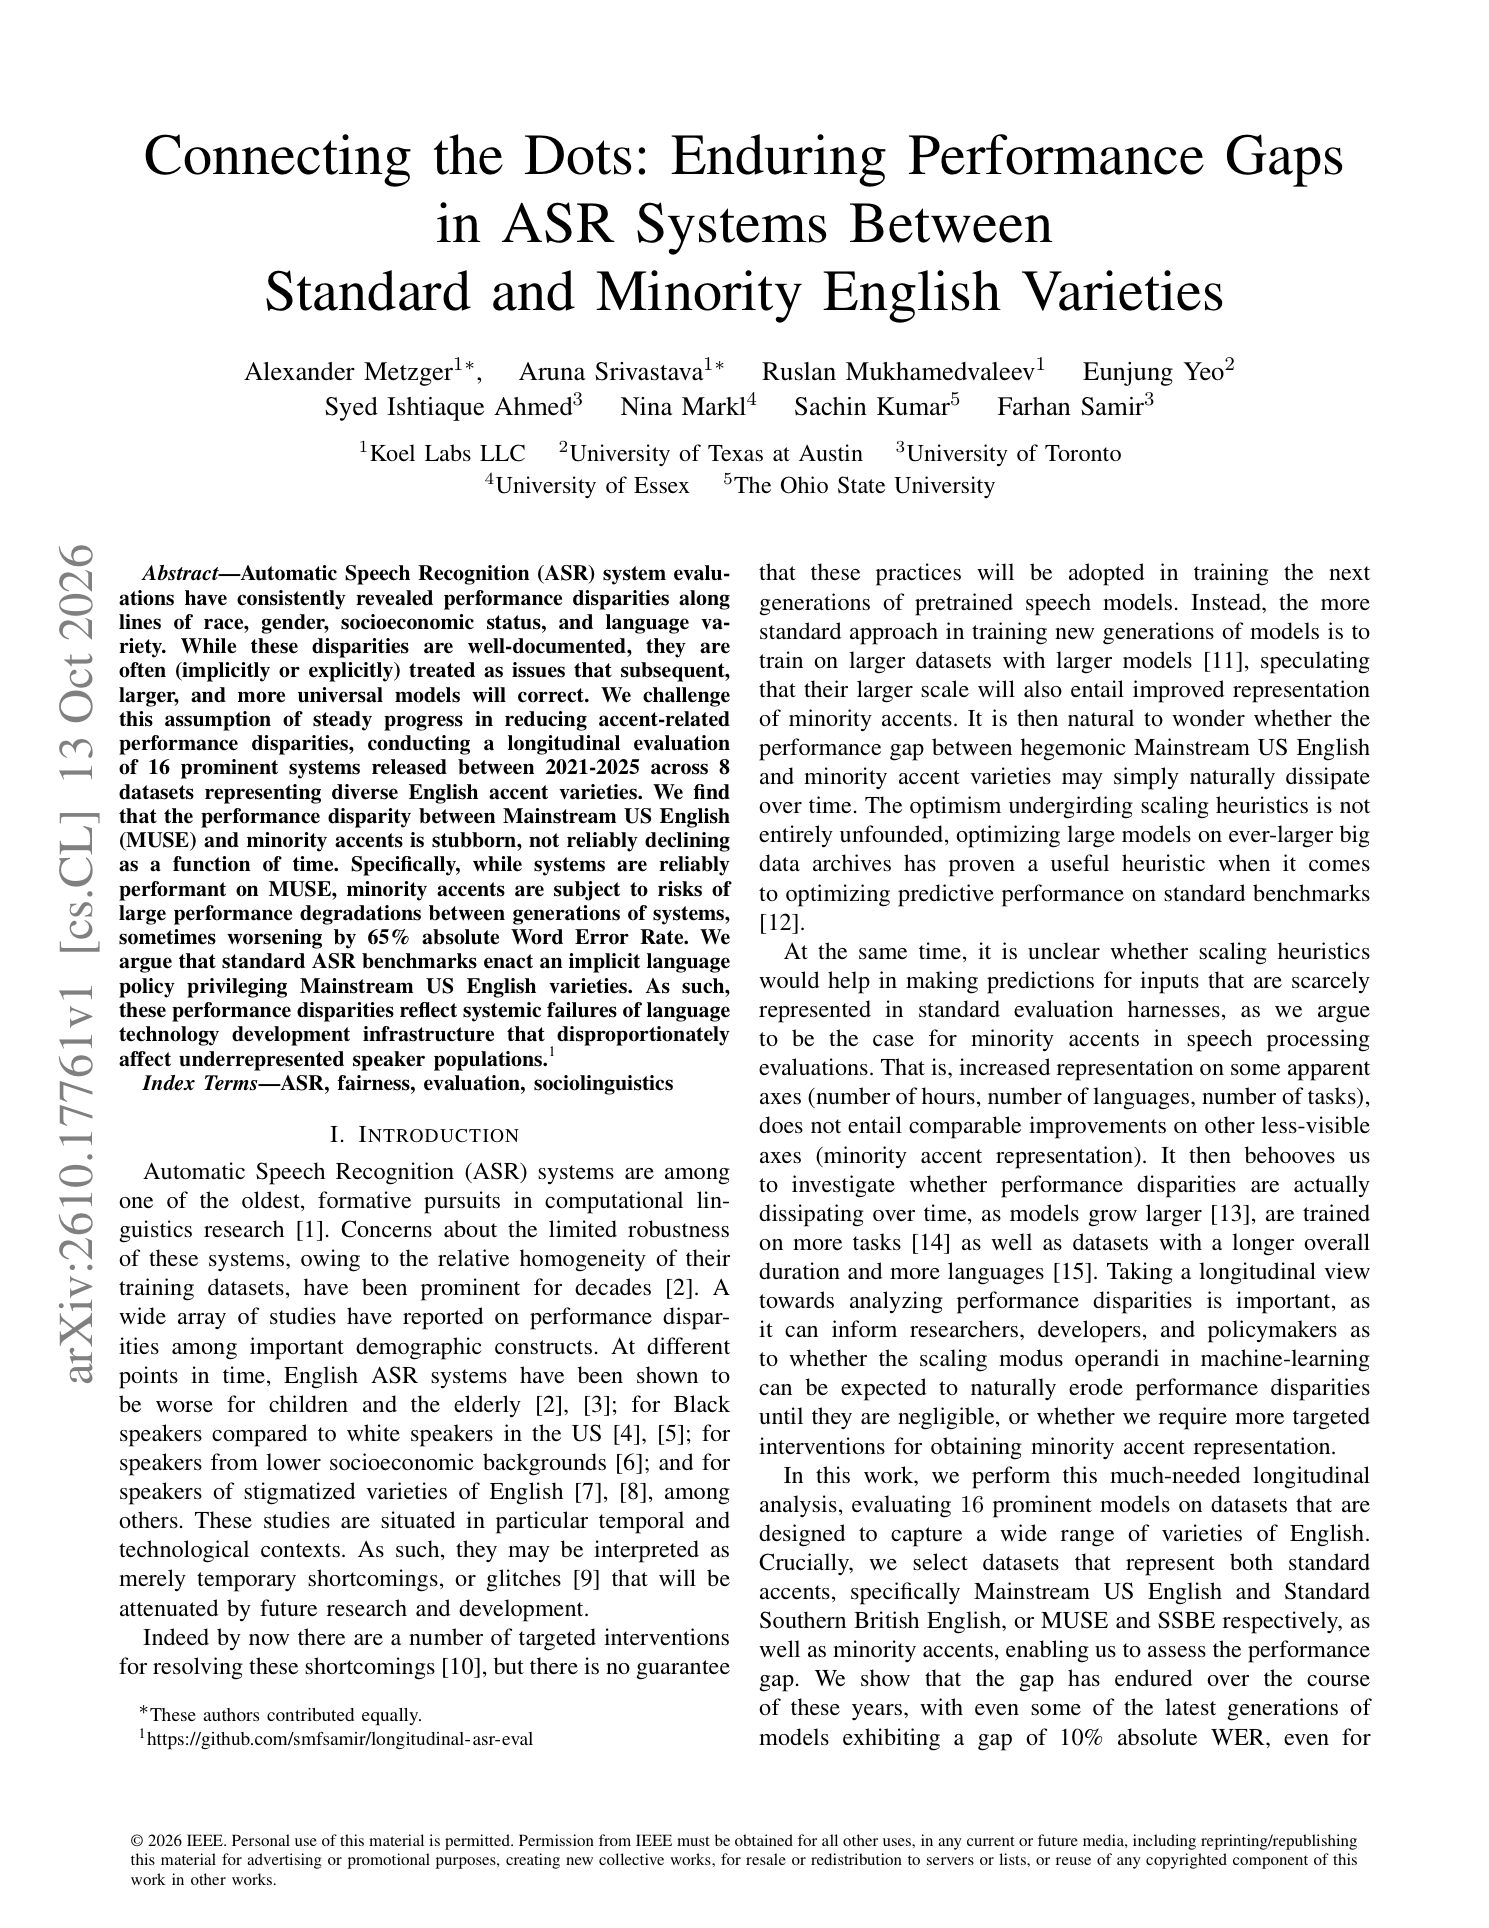
We show the speech recognition gap between Mainstream US English and minority accents is not closing as models scale.
We are a speech research lab building state-of-the-art models, tools, and datasets to make speech technology better.

Research
Models

XLSR-English-01 is our open phonetic transcription model. It transcribes speech into the International Phonetic Alphabet, capturing how words are actually pronounced rather than only what was said, for both standard and non-standard English.
To develop truly equitable speech technology, models should be able to accurately transcribe diverse speaker profiles, from aphasia to non-native speech.
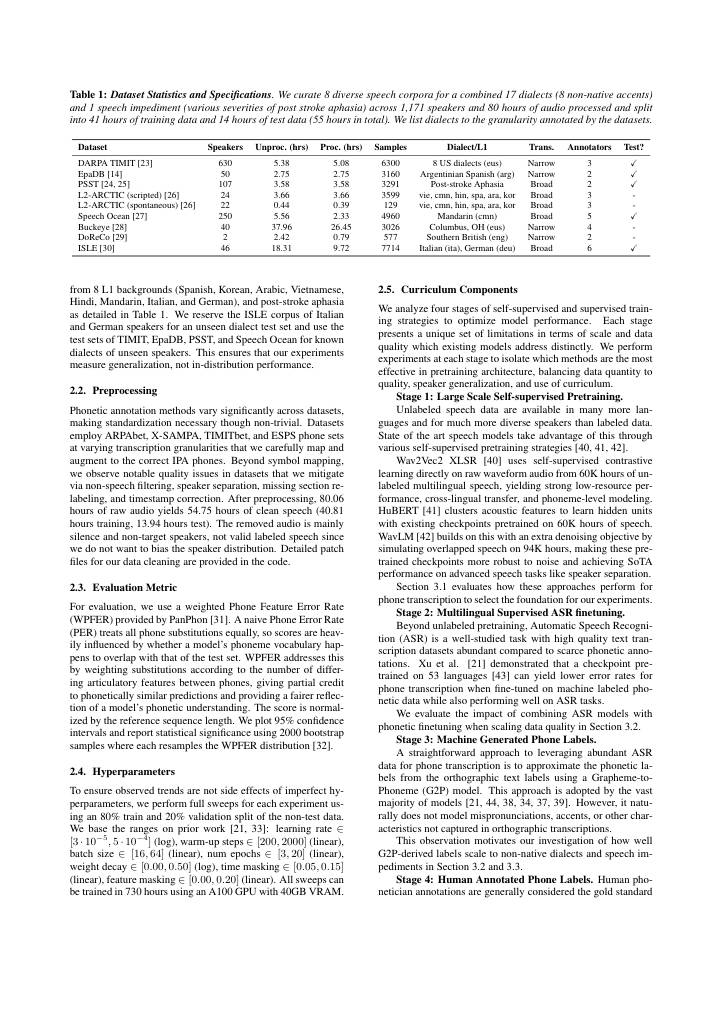
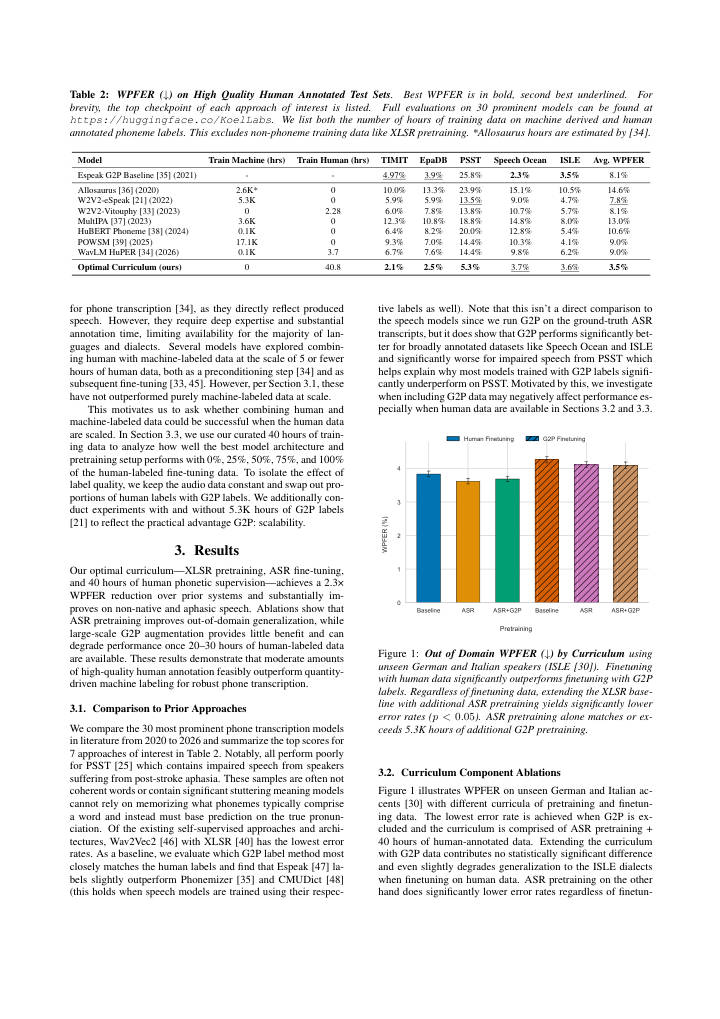
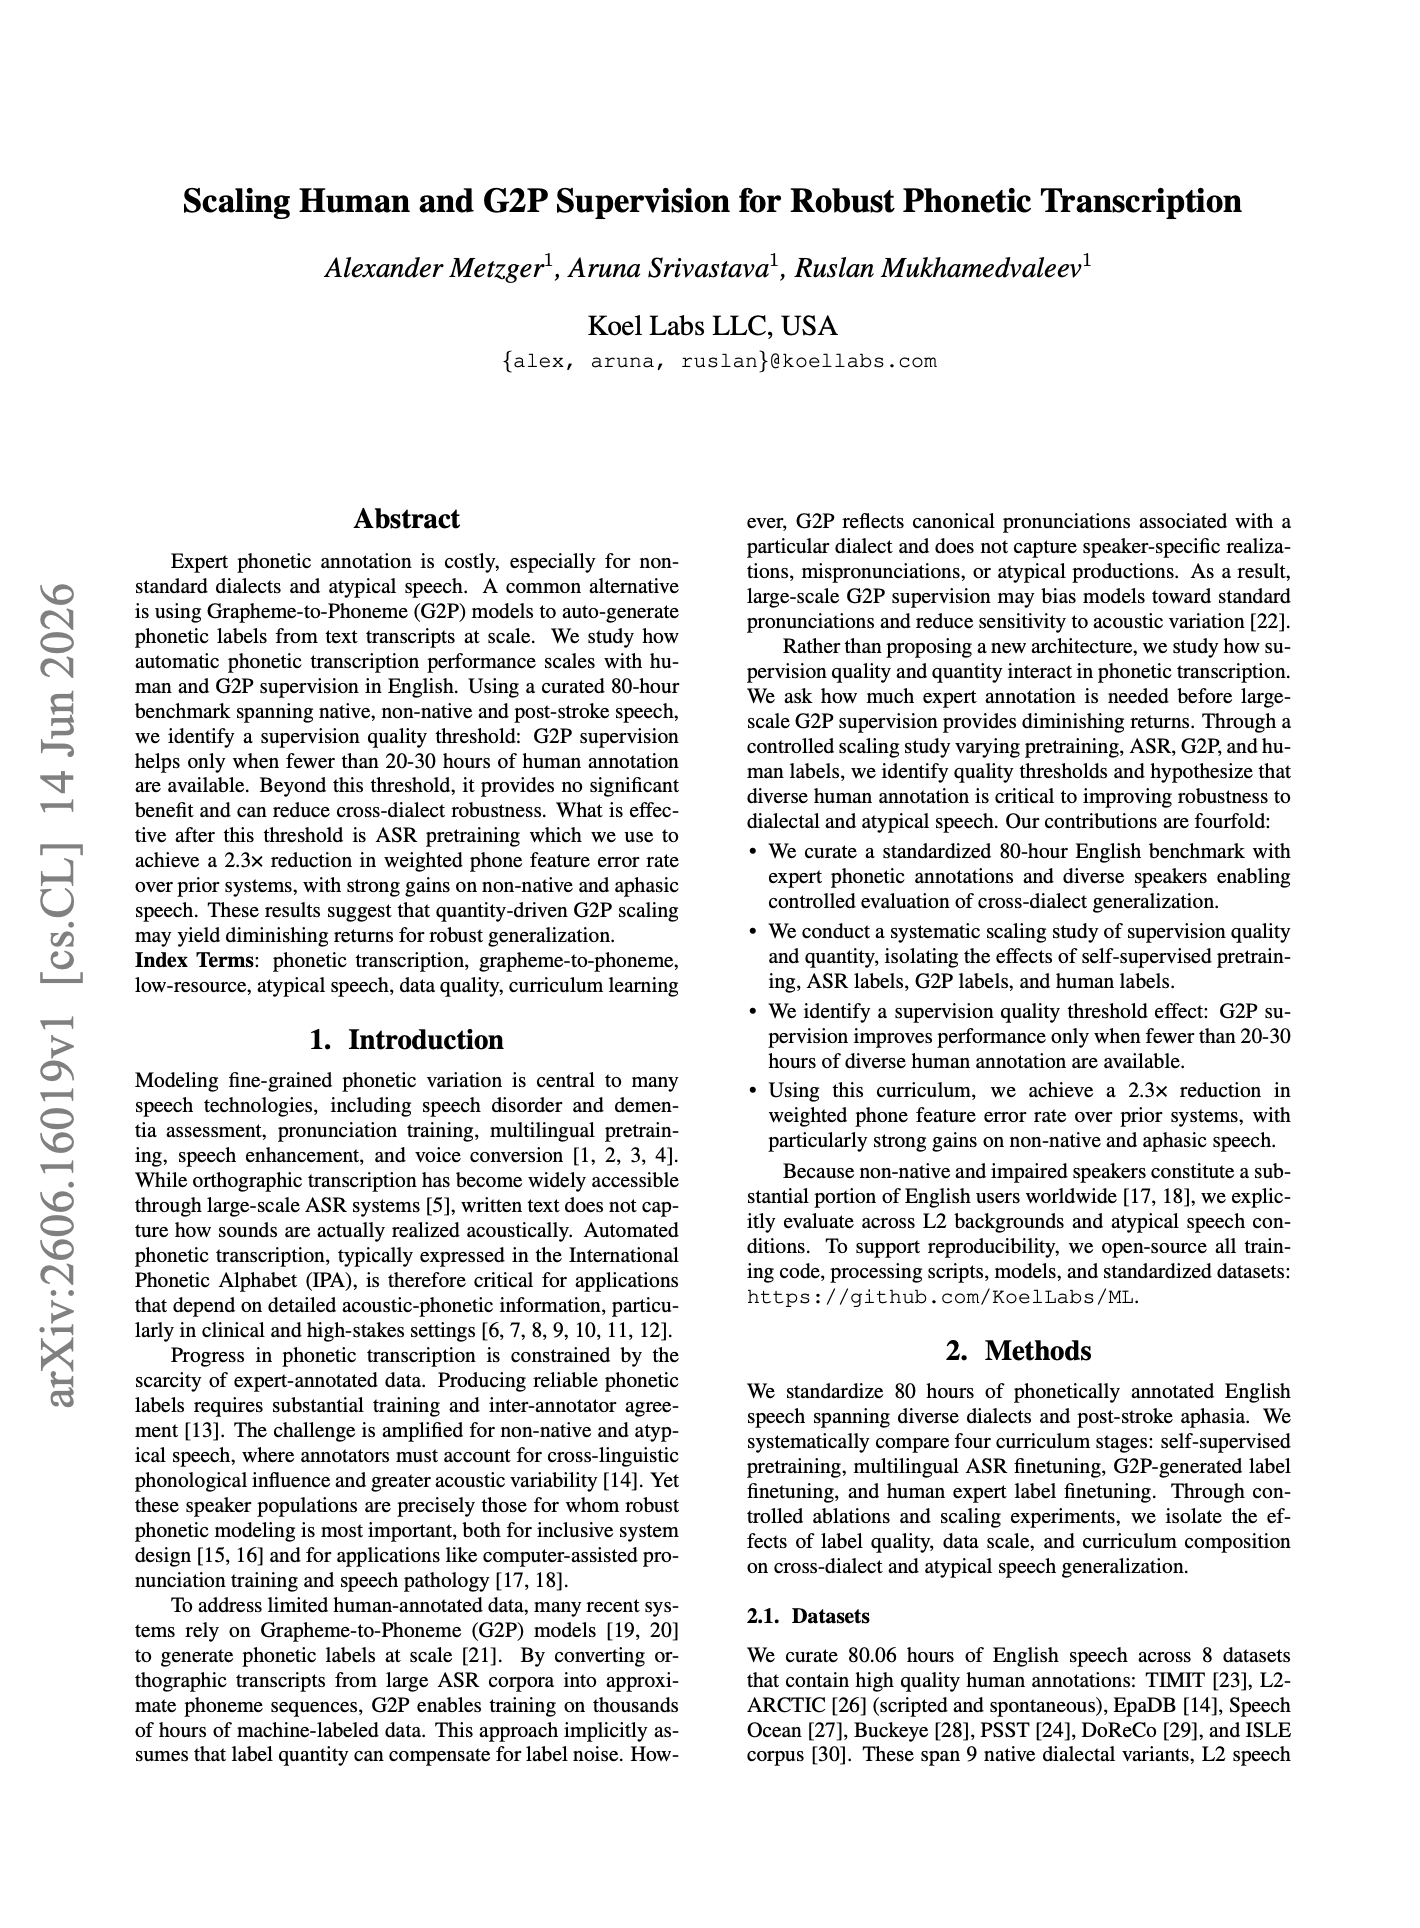
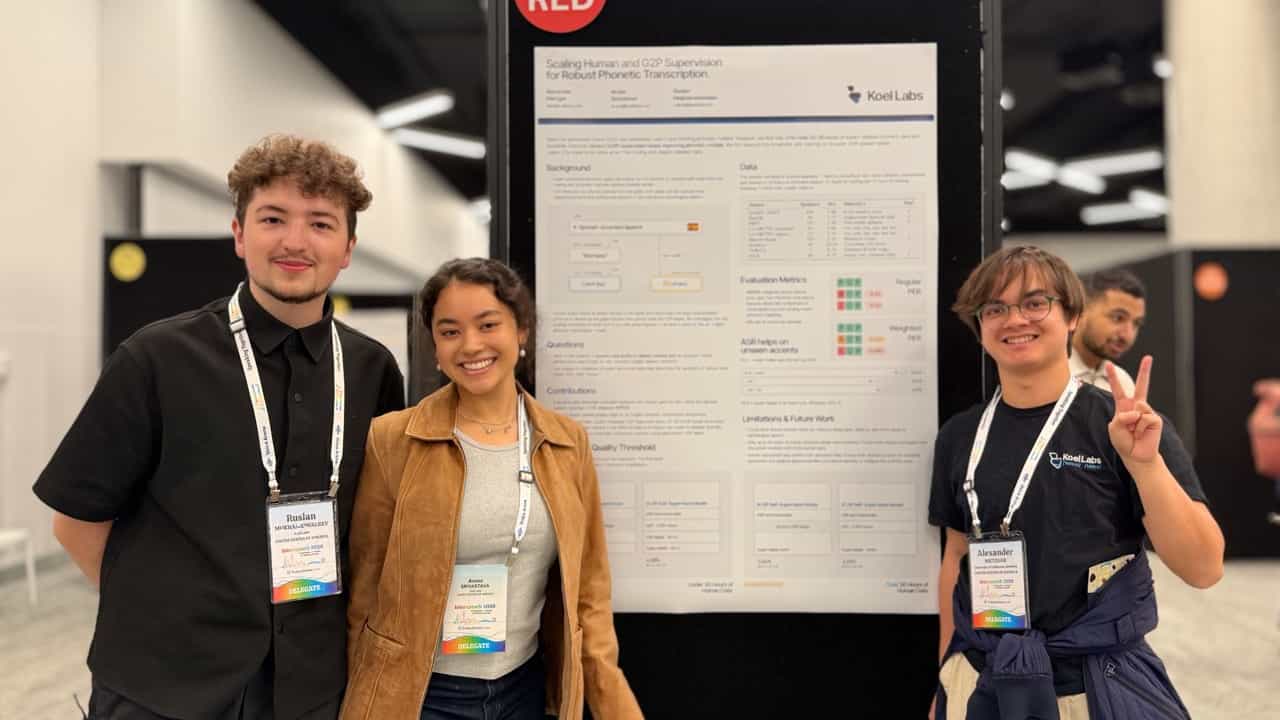
In our Interspeech 2026 paper, we curate an 80-hour benchmark spanning native, non-native, and post-stroke speech, and study how human and G2P supervision scale. With ASR pretraining, we achieve a 2.3× reduction in weighted phone feature error rate over prior systems, with the strongest gains on non-native and aphasic speech.
All training code, processing scripts, models, and standardized datasets are open source.
Real-world
XLSR-English-01, the state-of-the-art model for phonetic transcription of standard and non-standard English speech, is available on Hugging Face alongside our other models.
Slay Speech brings phonetic transcription together with language learning materials, giving learners word-by-word pronunciation feedback through short story-based lessons.
Our IPA transcription benchmark and leaderboard for native, non-native, and atypical speech are freely available. Get in touch to learn more about our datasets.